
Legal knowledge fine-tuning data generation
This template provides an end-to-end legal-data preparation workflow. It helps you build high-quality question-and-answer datasets from legal documents and fine-tune a model on the Hugging Face AutoTrain platform. It is suitable for custom large language models with domain-specific legal understanding, such as question-answering applications for labor disputes or contract disputes.
Template details
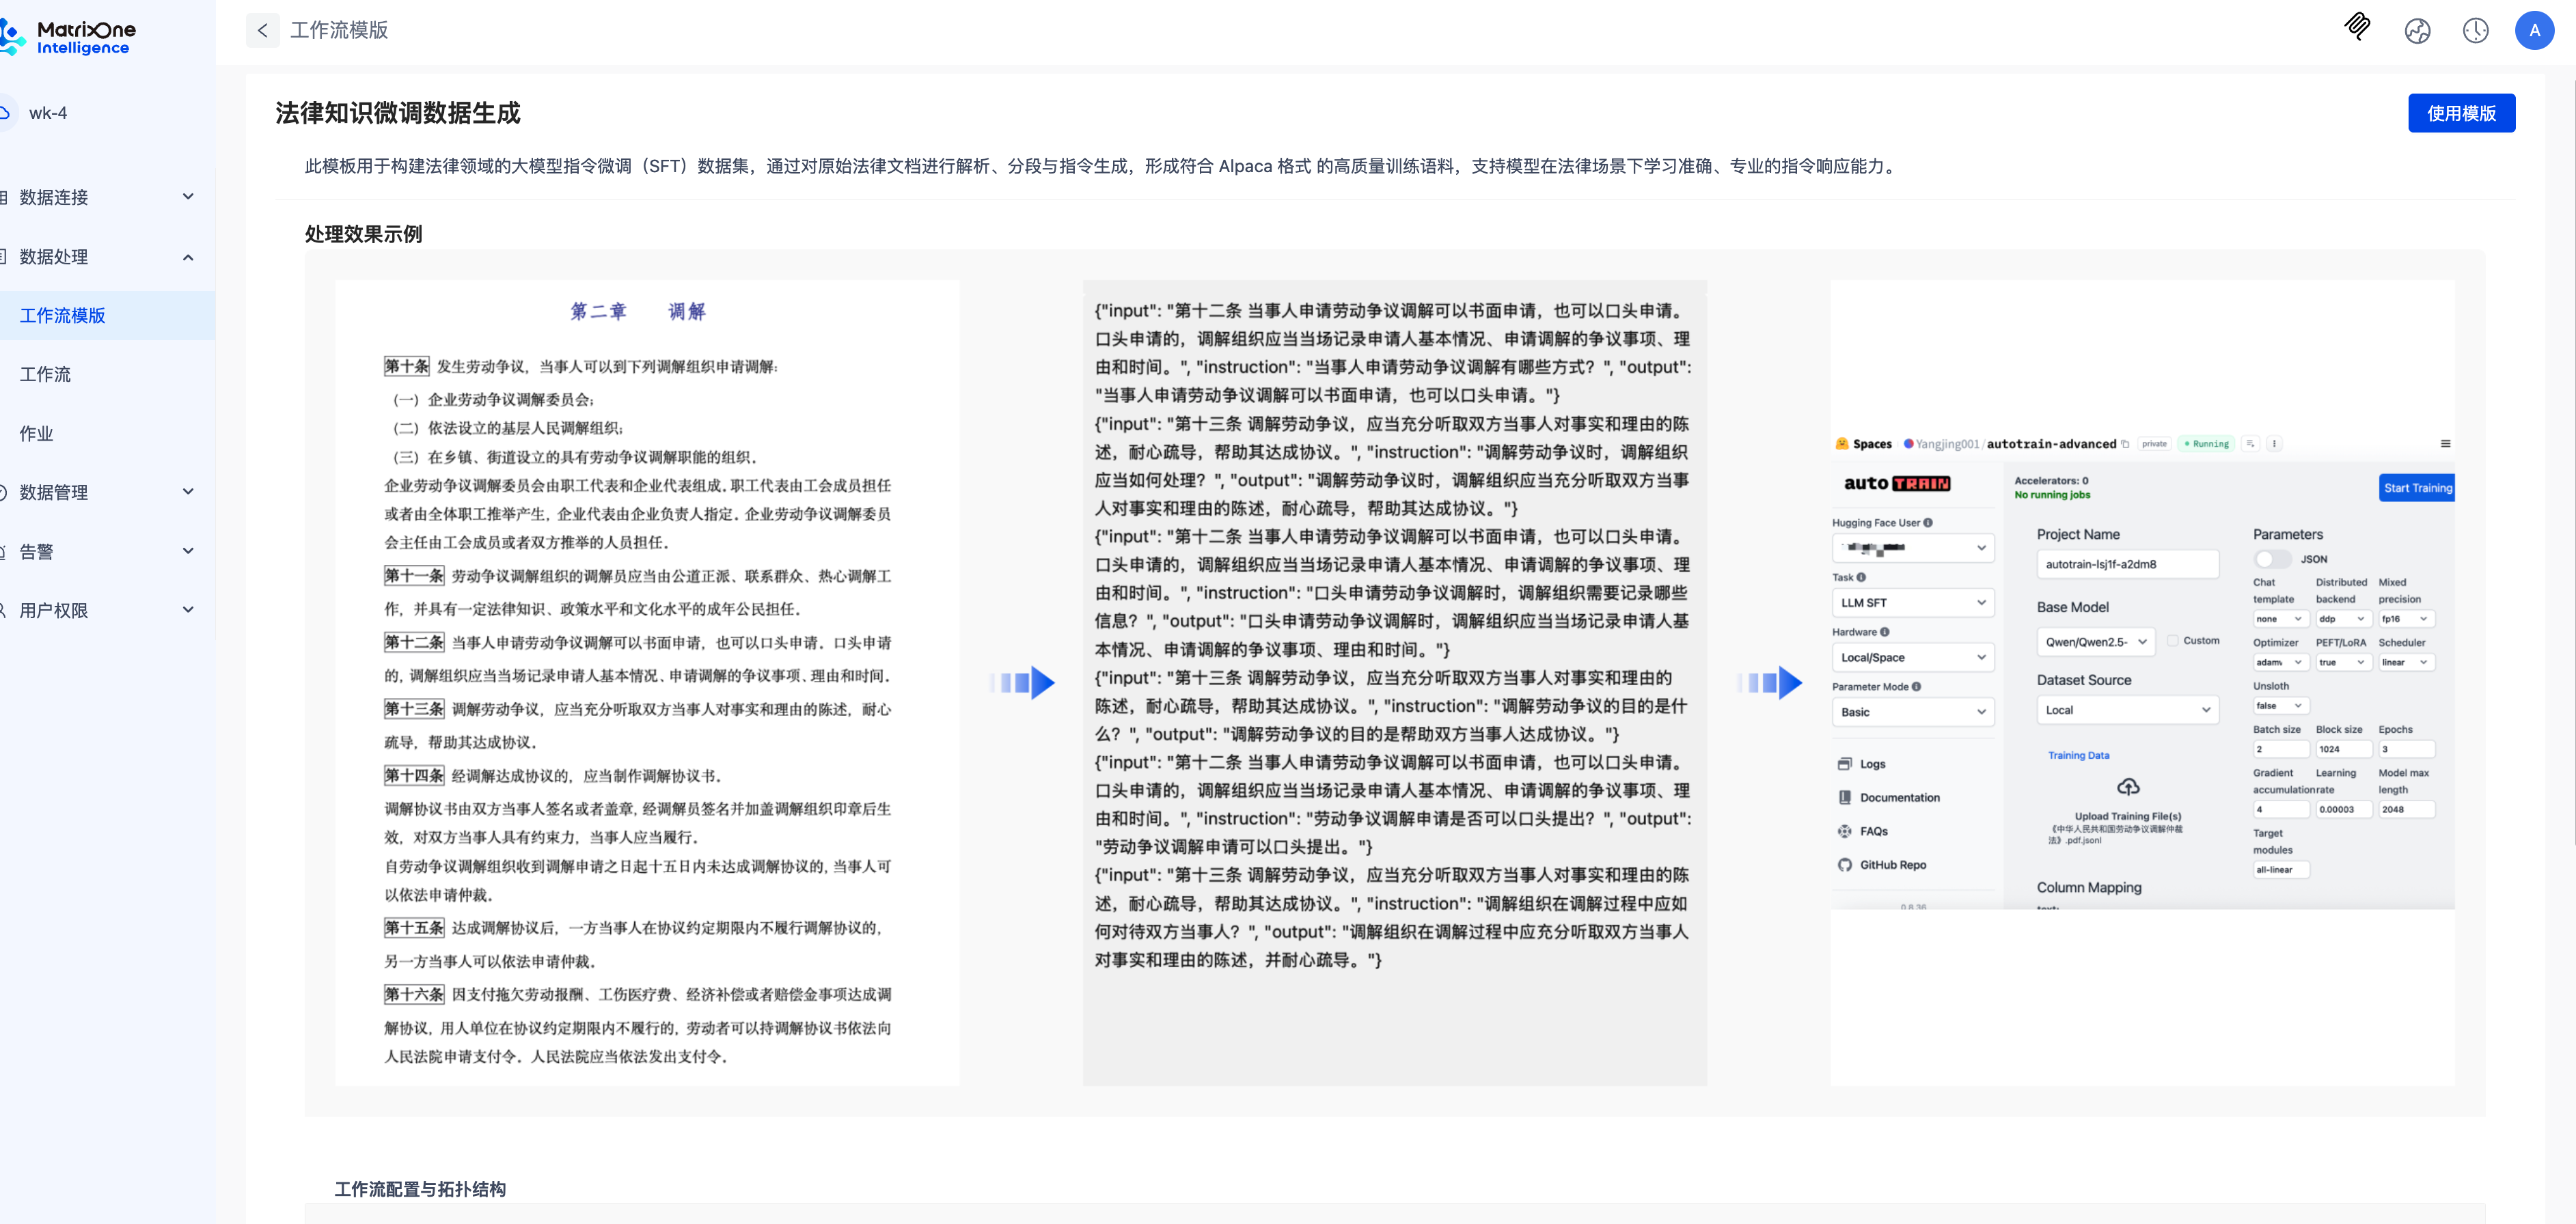
Select View details in the template list to open the template details page. It shows example processing results and the workflow topology.
Use the template
Select Legal knowledge fine-tuning data generation in the template list, then select Use template from the list or details page to create a data-processing task and its workflow.
The system includes sample data for initial testing.
Create the target location yourself.
Adjust parsing, augmentation, and other workflow-operator configuration as needed.
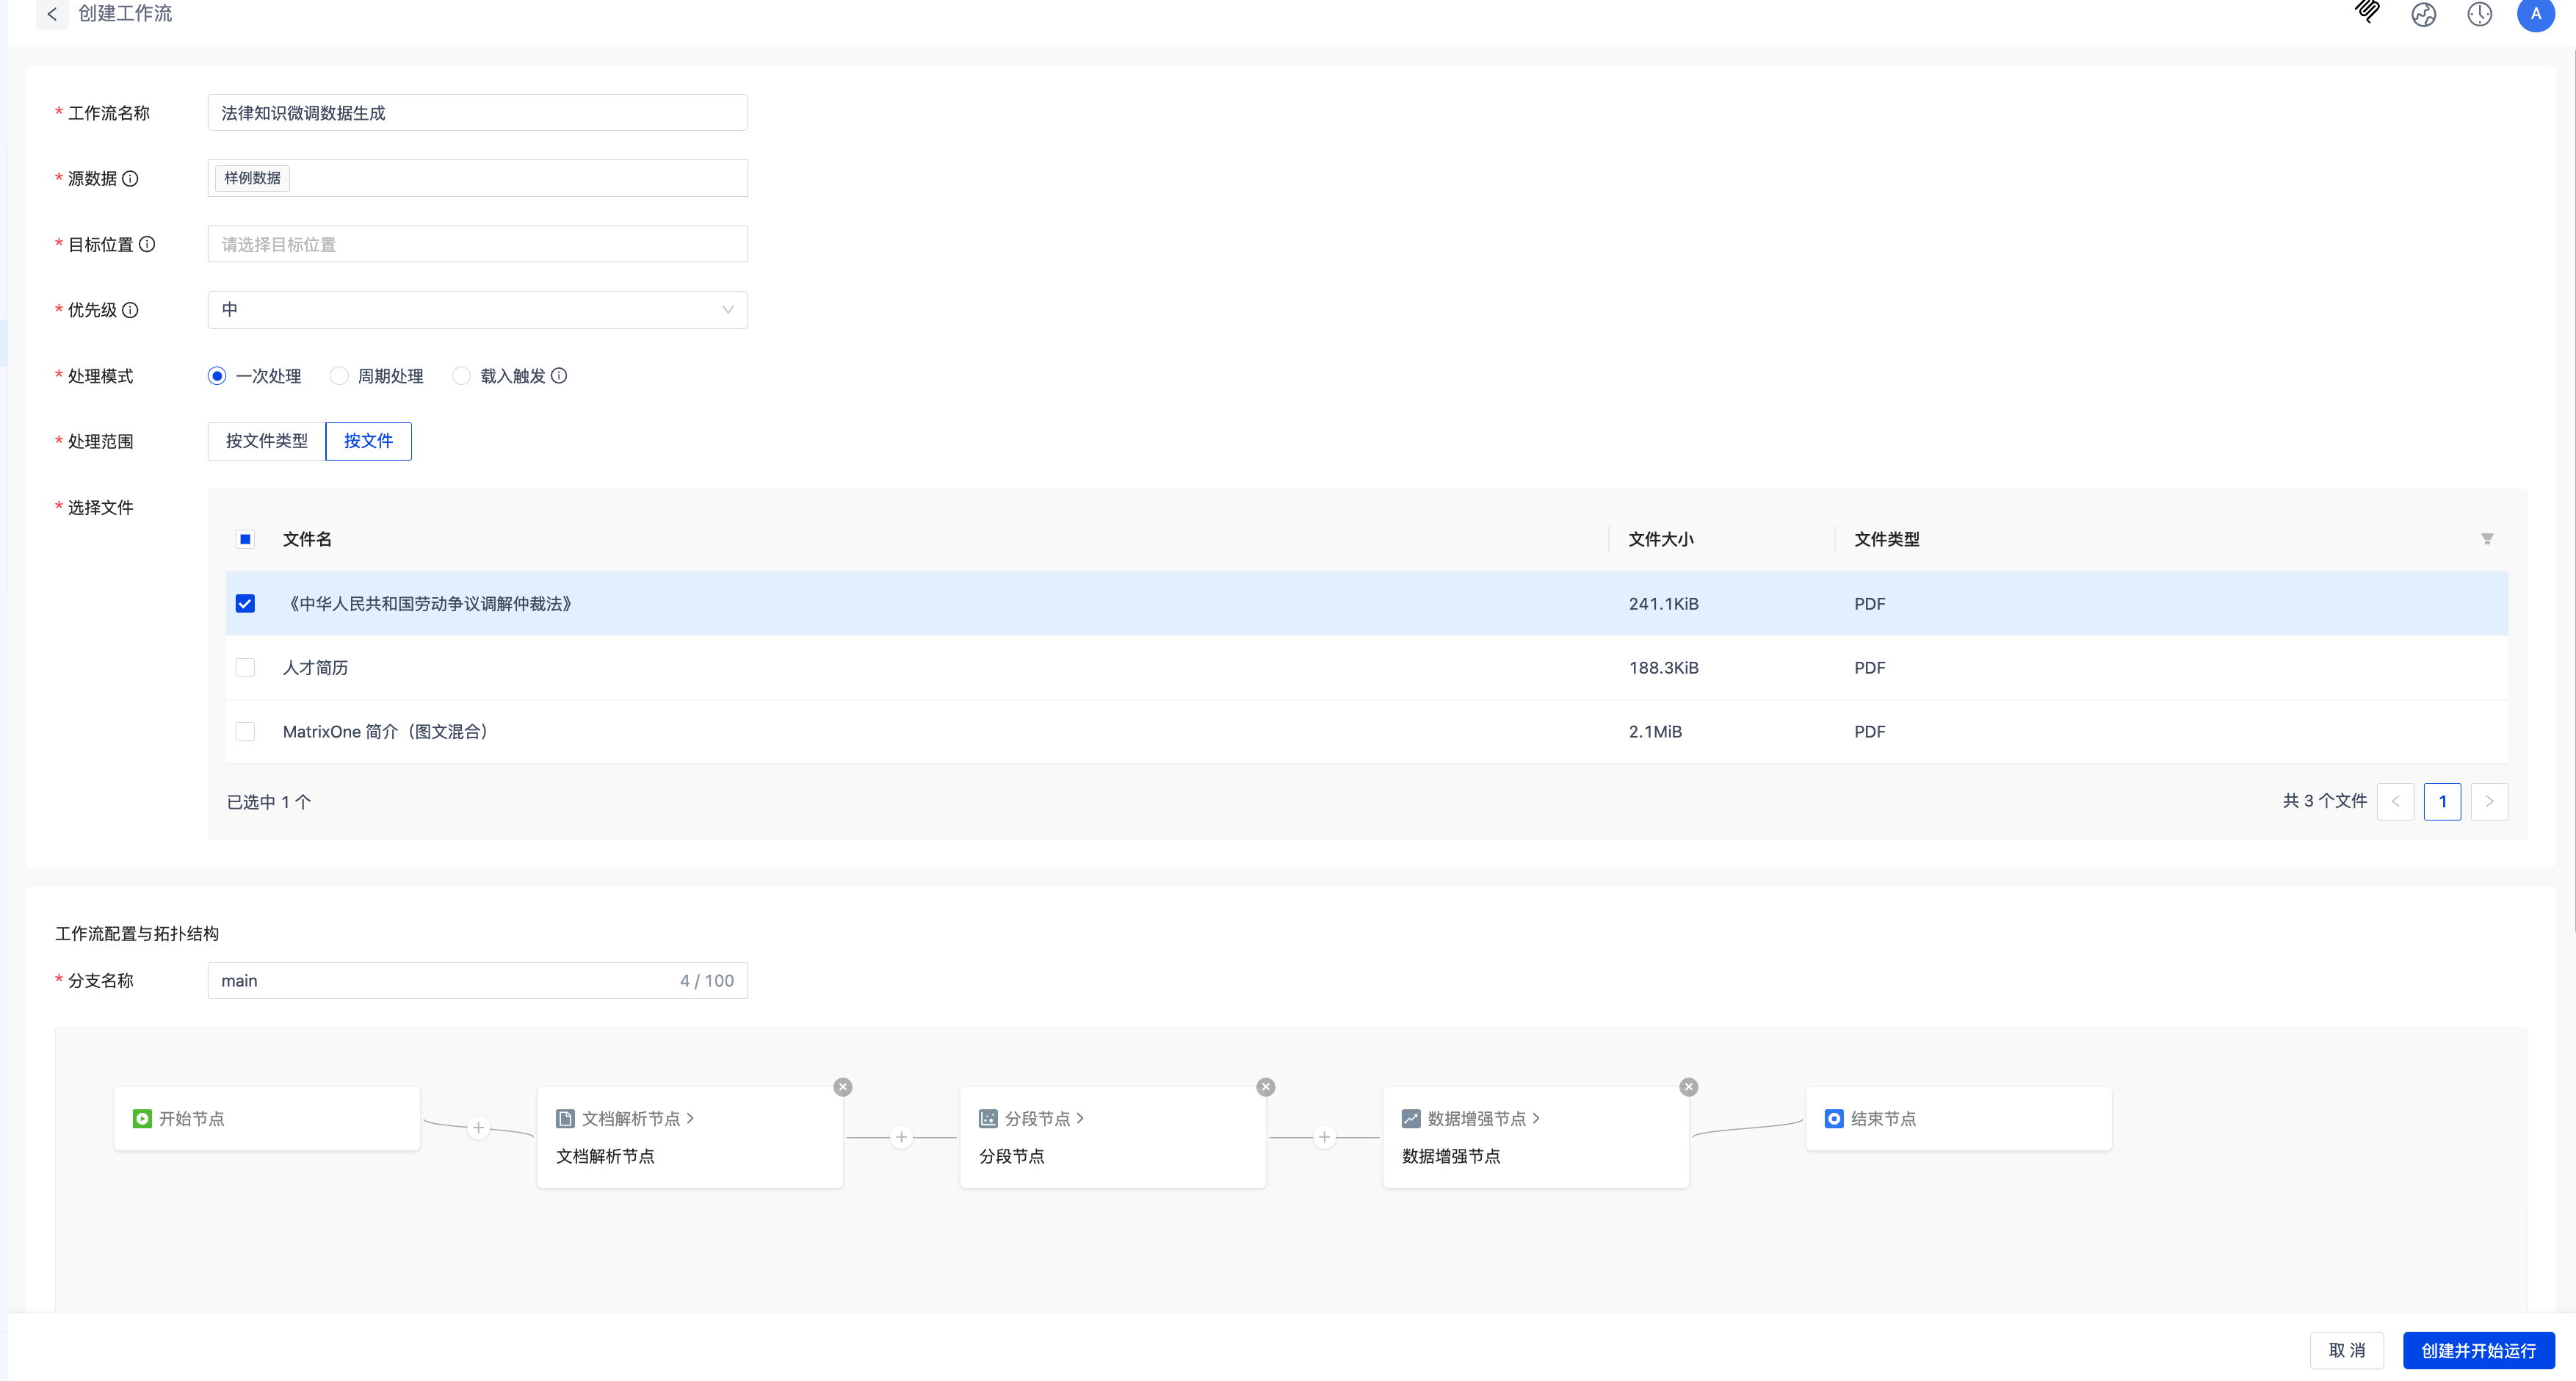
Select Create and start and wait for the workflow to finish.
View processing results
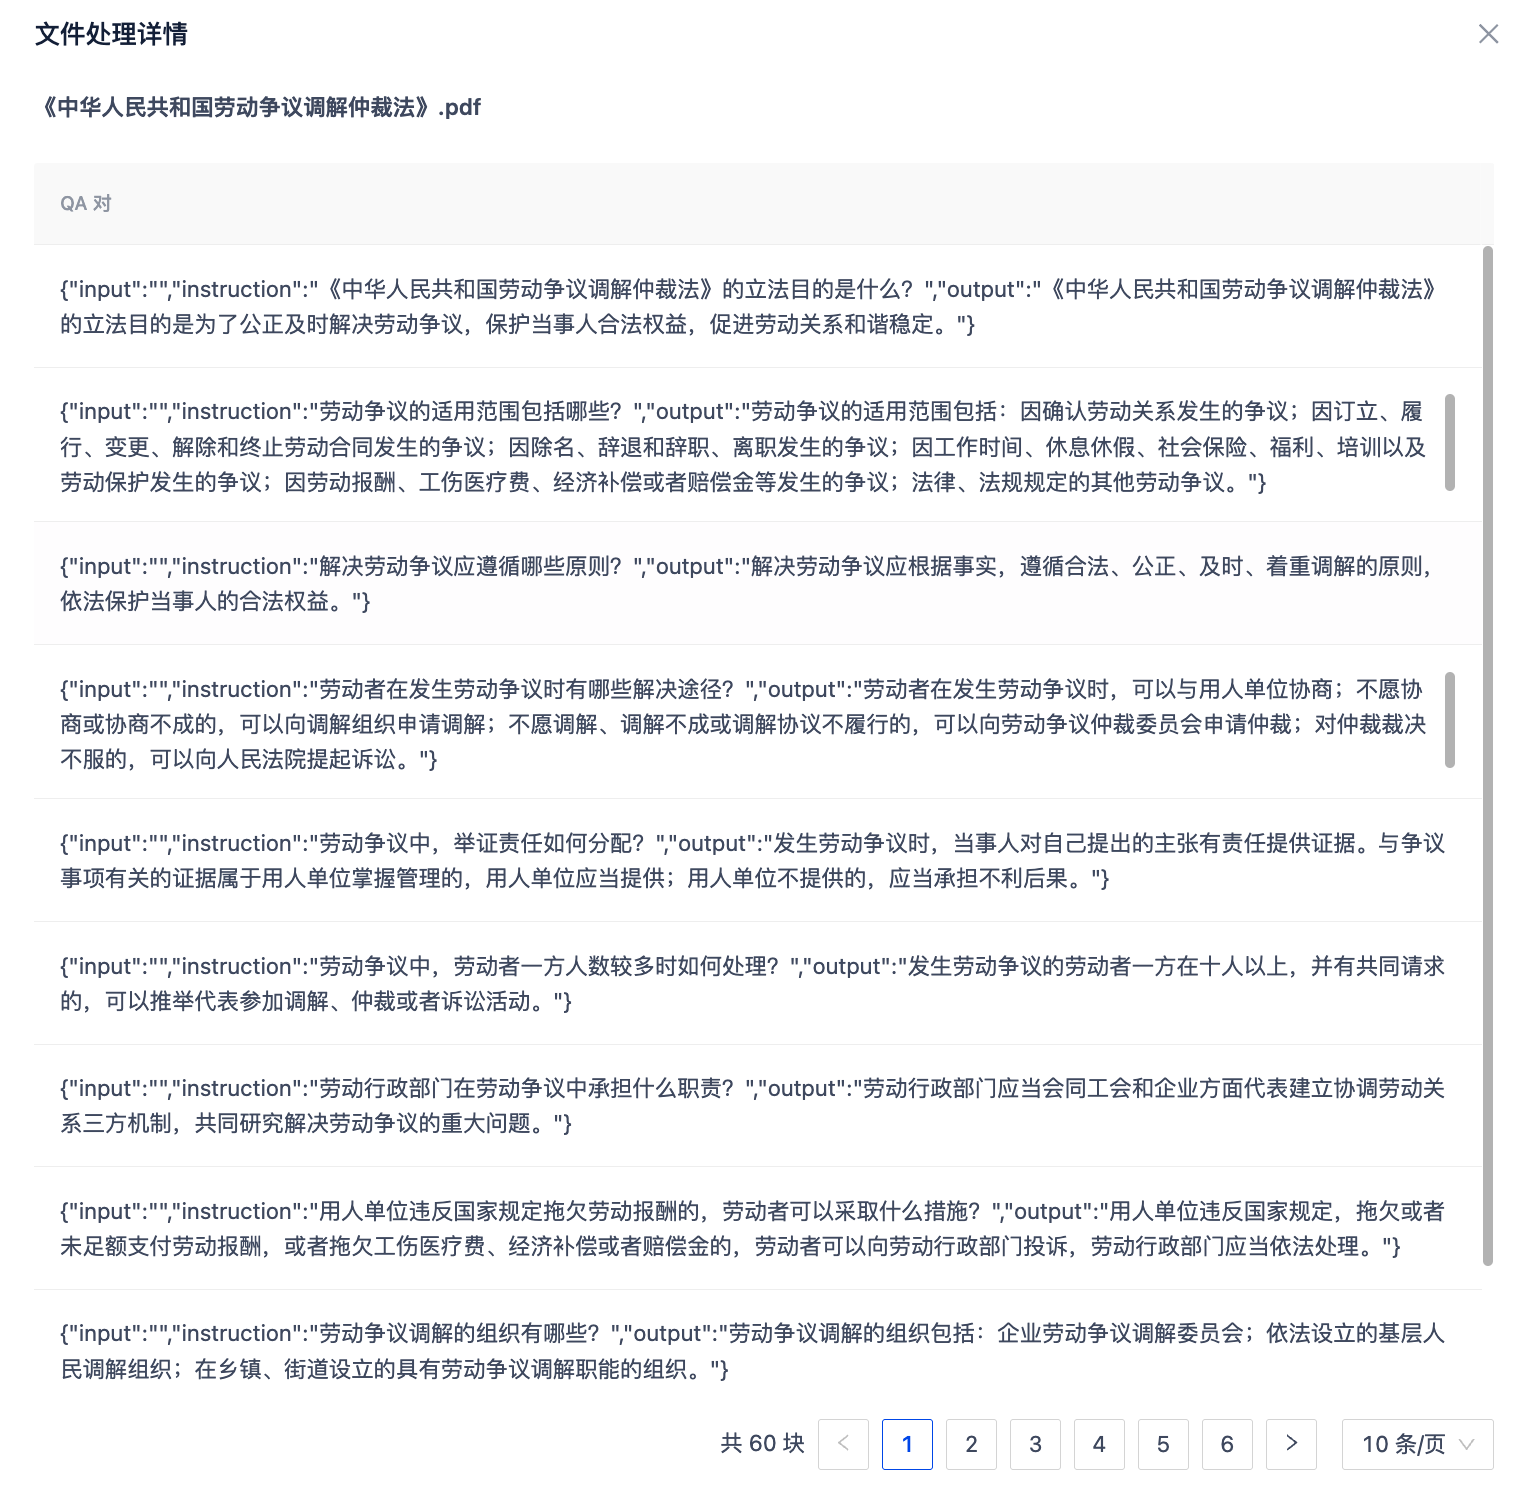
Open Catalog, find the target location selected by the workflow, and select the file name to view processing results.
Export data
After processing completes, export the dataset for subsequent model training. Select the download button to the right of the file in Catalog. After downloading and extracting it, you will obtain a standard question-and-answer dataset such as 中华人民共和国劳动争议调解仲裁法.pdf.jsonl.
Fine-tune a model with Hugging Face AutoTrain
Use Hugging Face AutoTrain to fine-tune a model online through a visual workflow.
Open AutoTrain.
Create a project and select Text Classification or Text Generation.
Upload
《中华人民共和国劳动争议调解仲裁法》.pdf.jsonlto the project.Configure training epochs, learning rate, and a base model, such as Mistral or Gemma.
Select
Start Trainingto begin fine-tuning.
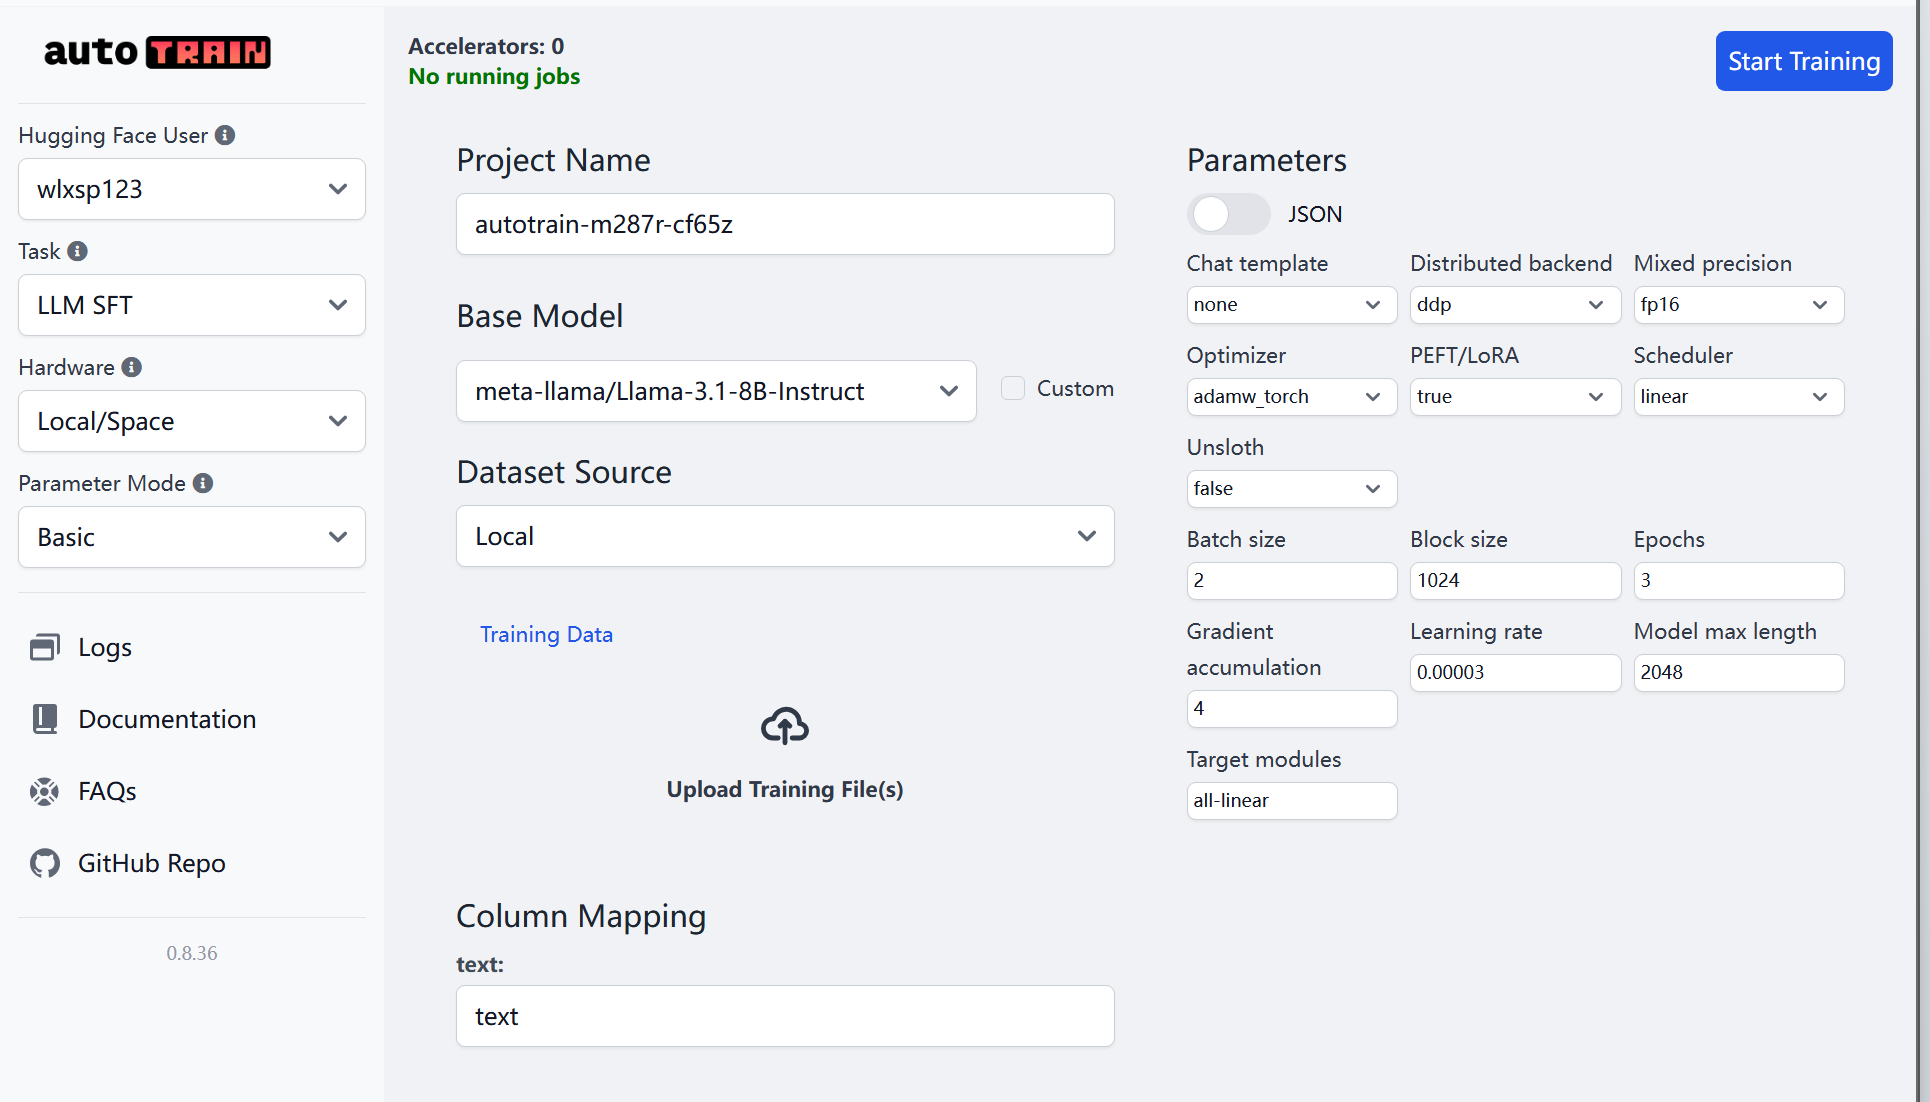
AutoTrain deploys the environment and runs training. When training finishes, you have a fine-tuned model for legal question answering that you can deploy or call from the platform.