

Resume information extraction
This template is for intelligent document processing (IDP). It builds an automated workflow that parses resumes and extracts structured information, converting resumes into database-ready data for talent screening, profile analysis, and recruitment applications.
Template details
Select View details in the template list to open the template details page. It shows example processing results and the workflow topology.
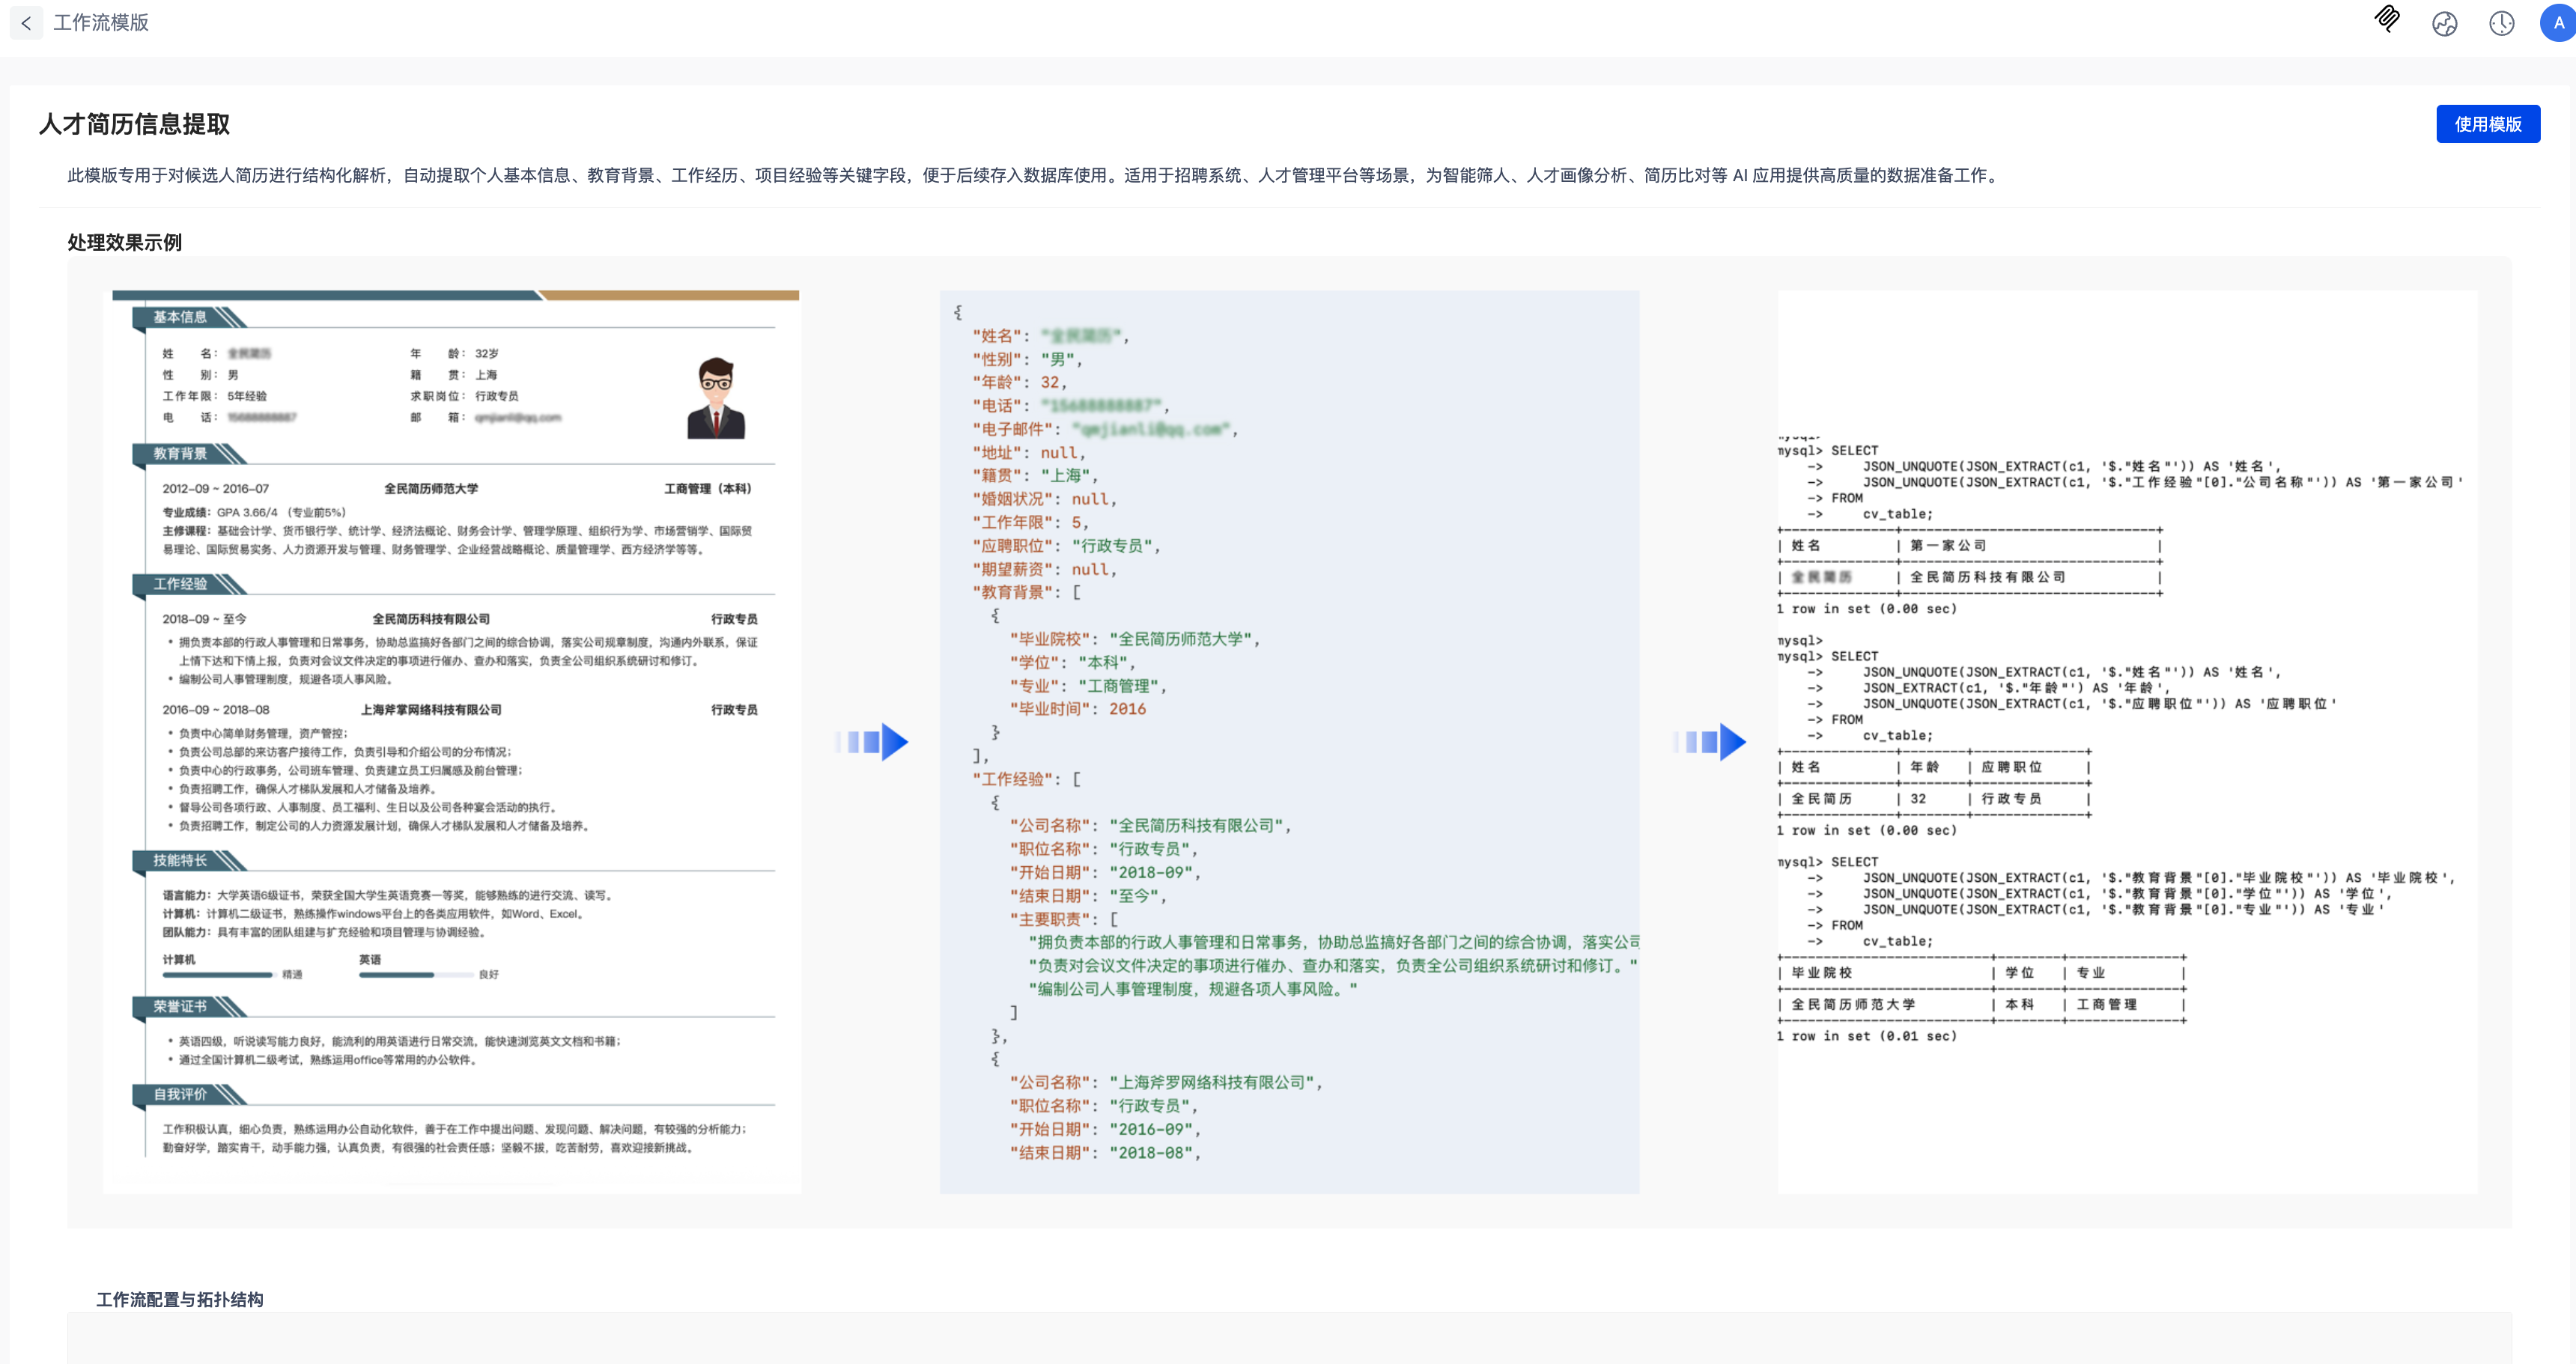
Use the template
Select Resume information extraction in the template list, then select Use template from the list or details page to create a data-processing task and its workflow.
The system includes sample data for initial testing.
Create the target location yourself.
Adjust parsing, extraction, and other workflow-operator configuration as needed.
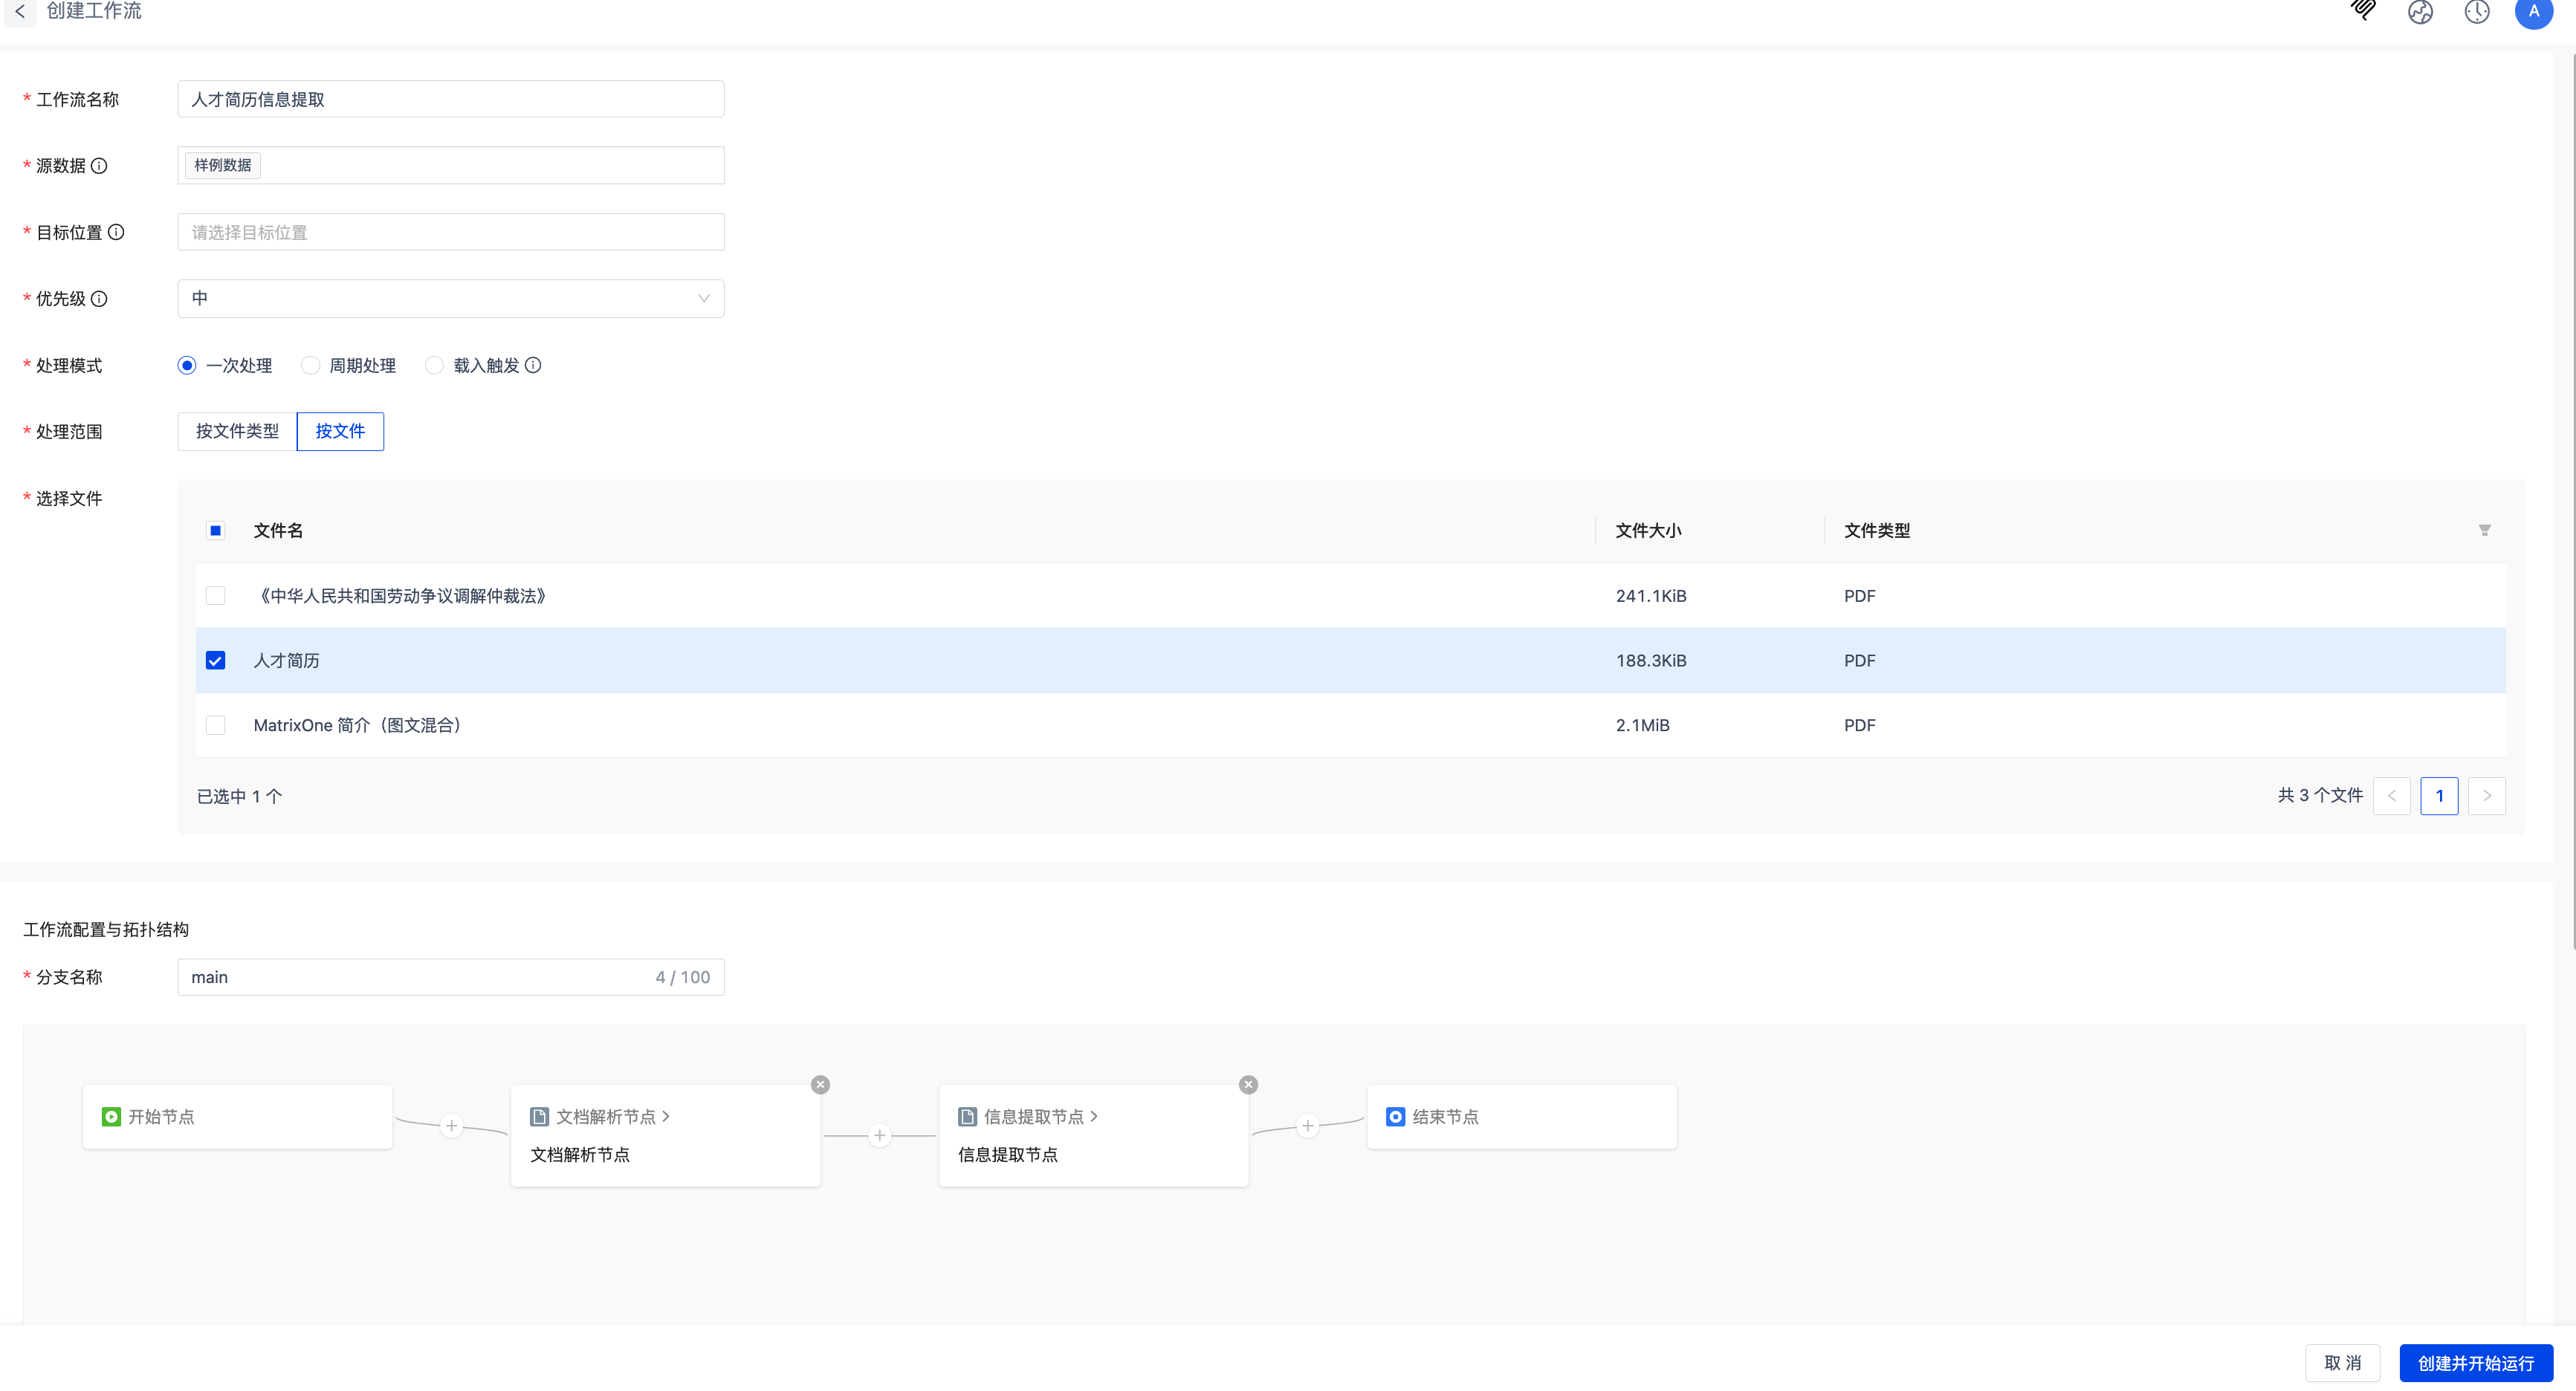
Select Create and start and wait for the workflow to finish.
View processing results
Open Catalog, find the target location selected by the workflow, and select the file name to view processing results.
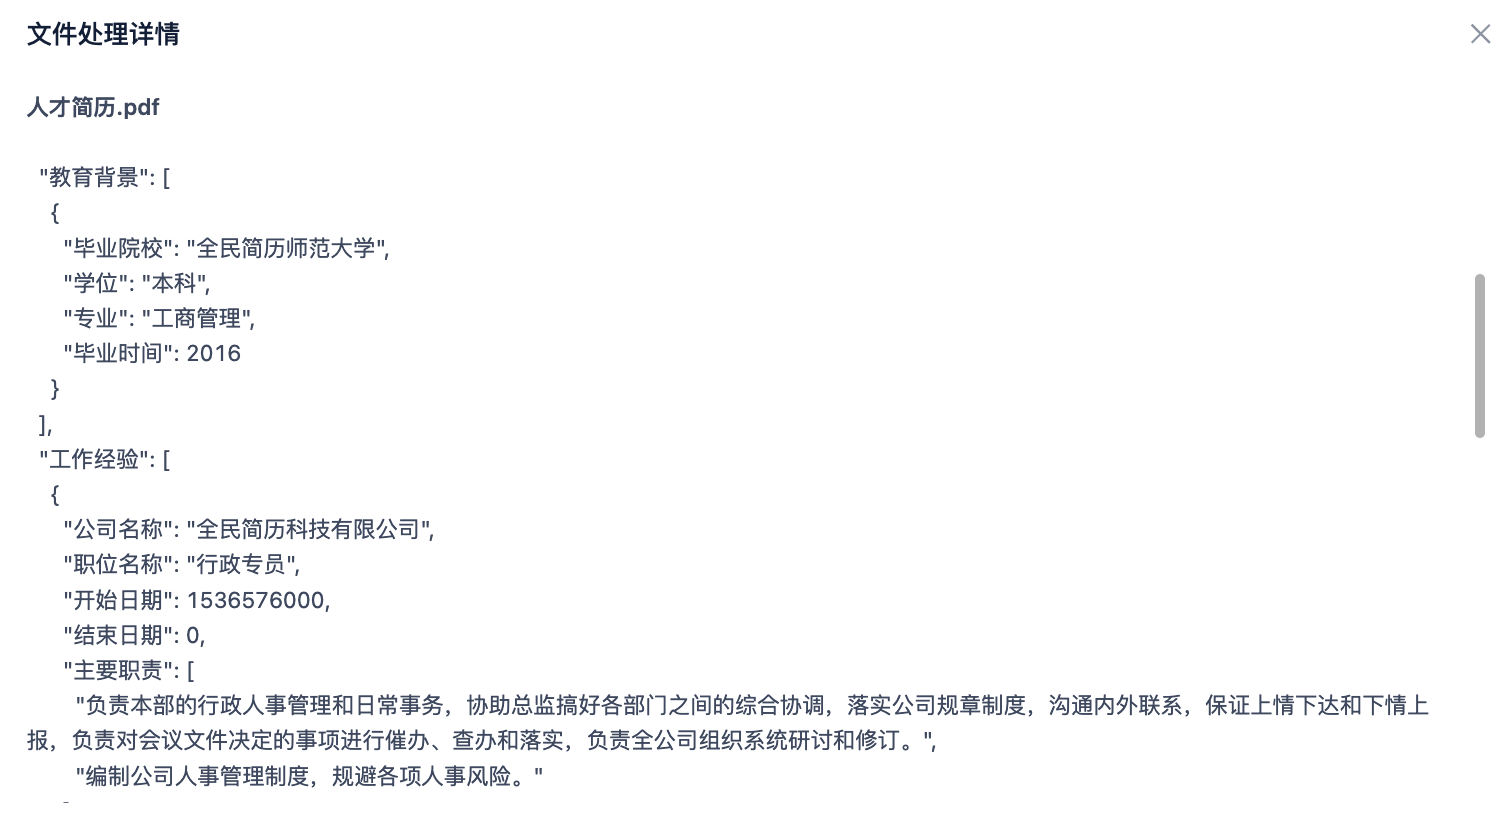
Export data
After processing completes, export the extracted JSON document for later retrieval. Select the download button to the right of the file in Catalog. After downloading and extracting it, you will obtain a JSON file such as 人才简历.pdf.json.
Query information
After export, import the JSON file into a database and query candidate data with SQL for multidimensional filtering and analysis. The following example uses MatrixOne. If you have not created an instance, see Database instances.
Create a table after connecting to the instance:
mysql> CREATE TABLE my_json_data (
    ->     id INT AUTO_INCREMENT PRIMARY KEY,
    ->     content JSON
    -> );
Query OK, 0 rows affected (0.34 sec)
Next, create a my_data.py script to insert and query JSON data.
import json
import pymysql

# Read the JSON file
with open("/Users/admin/Downloads/人才简历.pdf-0198acba-2183-7291-9b9c-d32d5c3eb9f5/人才简历.pdf.json", "r", encoding="utf-8") as f:
    json_data = json.load(f)

# Connect to MatrixOne
conn = pymysql.connect(
    host="xxx",
    port=6001,
    user="01946e41-6c67-7246-b36a-72619e9fxxxx:admin:accountadmin",
    password="xxx",
    database="db1",
    charset="utf8mb4"
)
cursor = conn.cursor()

# Insert JSON data
insert_sql = "INSERT INTO my_json_data (content) VALUES (%s)"
cursor.execute(insert_sql, (json.dumps(json_data, ensure_ascii=False),))
conn.commit()
print("✅ JSON 数据已插入 MatrixOne")

# Query data
query_sql = """
SELECT
    JSON_UNQUOTE(JSON_EXTRACT(content, '$."姓名"')) AS '姓名',
    JSON_EXTRACT(content, '$."年龄"') AS '年龄',
    JSON_UNQUOTE(JSON_EXTRACT(content, '$."求职意向"')) AS '应聘职位'
FROM my_json_data;
"""

cursor.execute(query_sql)
rows = cursor.fetchall()

# Print the result
print("\n🎯 查询结果:")
for name, age, job in rows:
    print(f"姓名:{name}, 年龄:{age}, 应聘职位:{job}")

# Close the connection
cursor.close()
conn.close()
Run the script:
>python my_data.py

✅ JSON 数据已插入 MatrixOne

🎯 查询结果:
姓名: 全民简历, 年龄: 32, 应聘职位: 行政专员