

Workflow templates
Templates provide connected processing steps. Choose one for your task, load it onto the canvas, and configure your sources, models, and output location.
Select and use a template
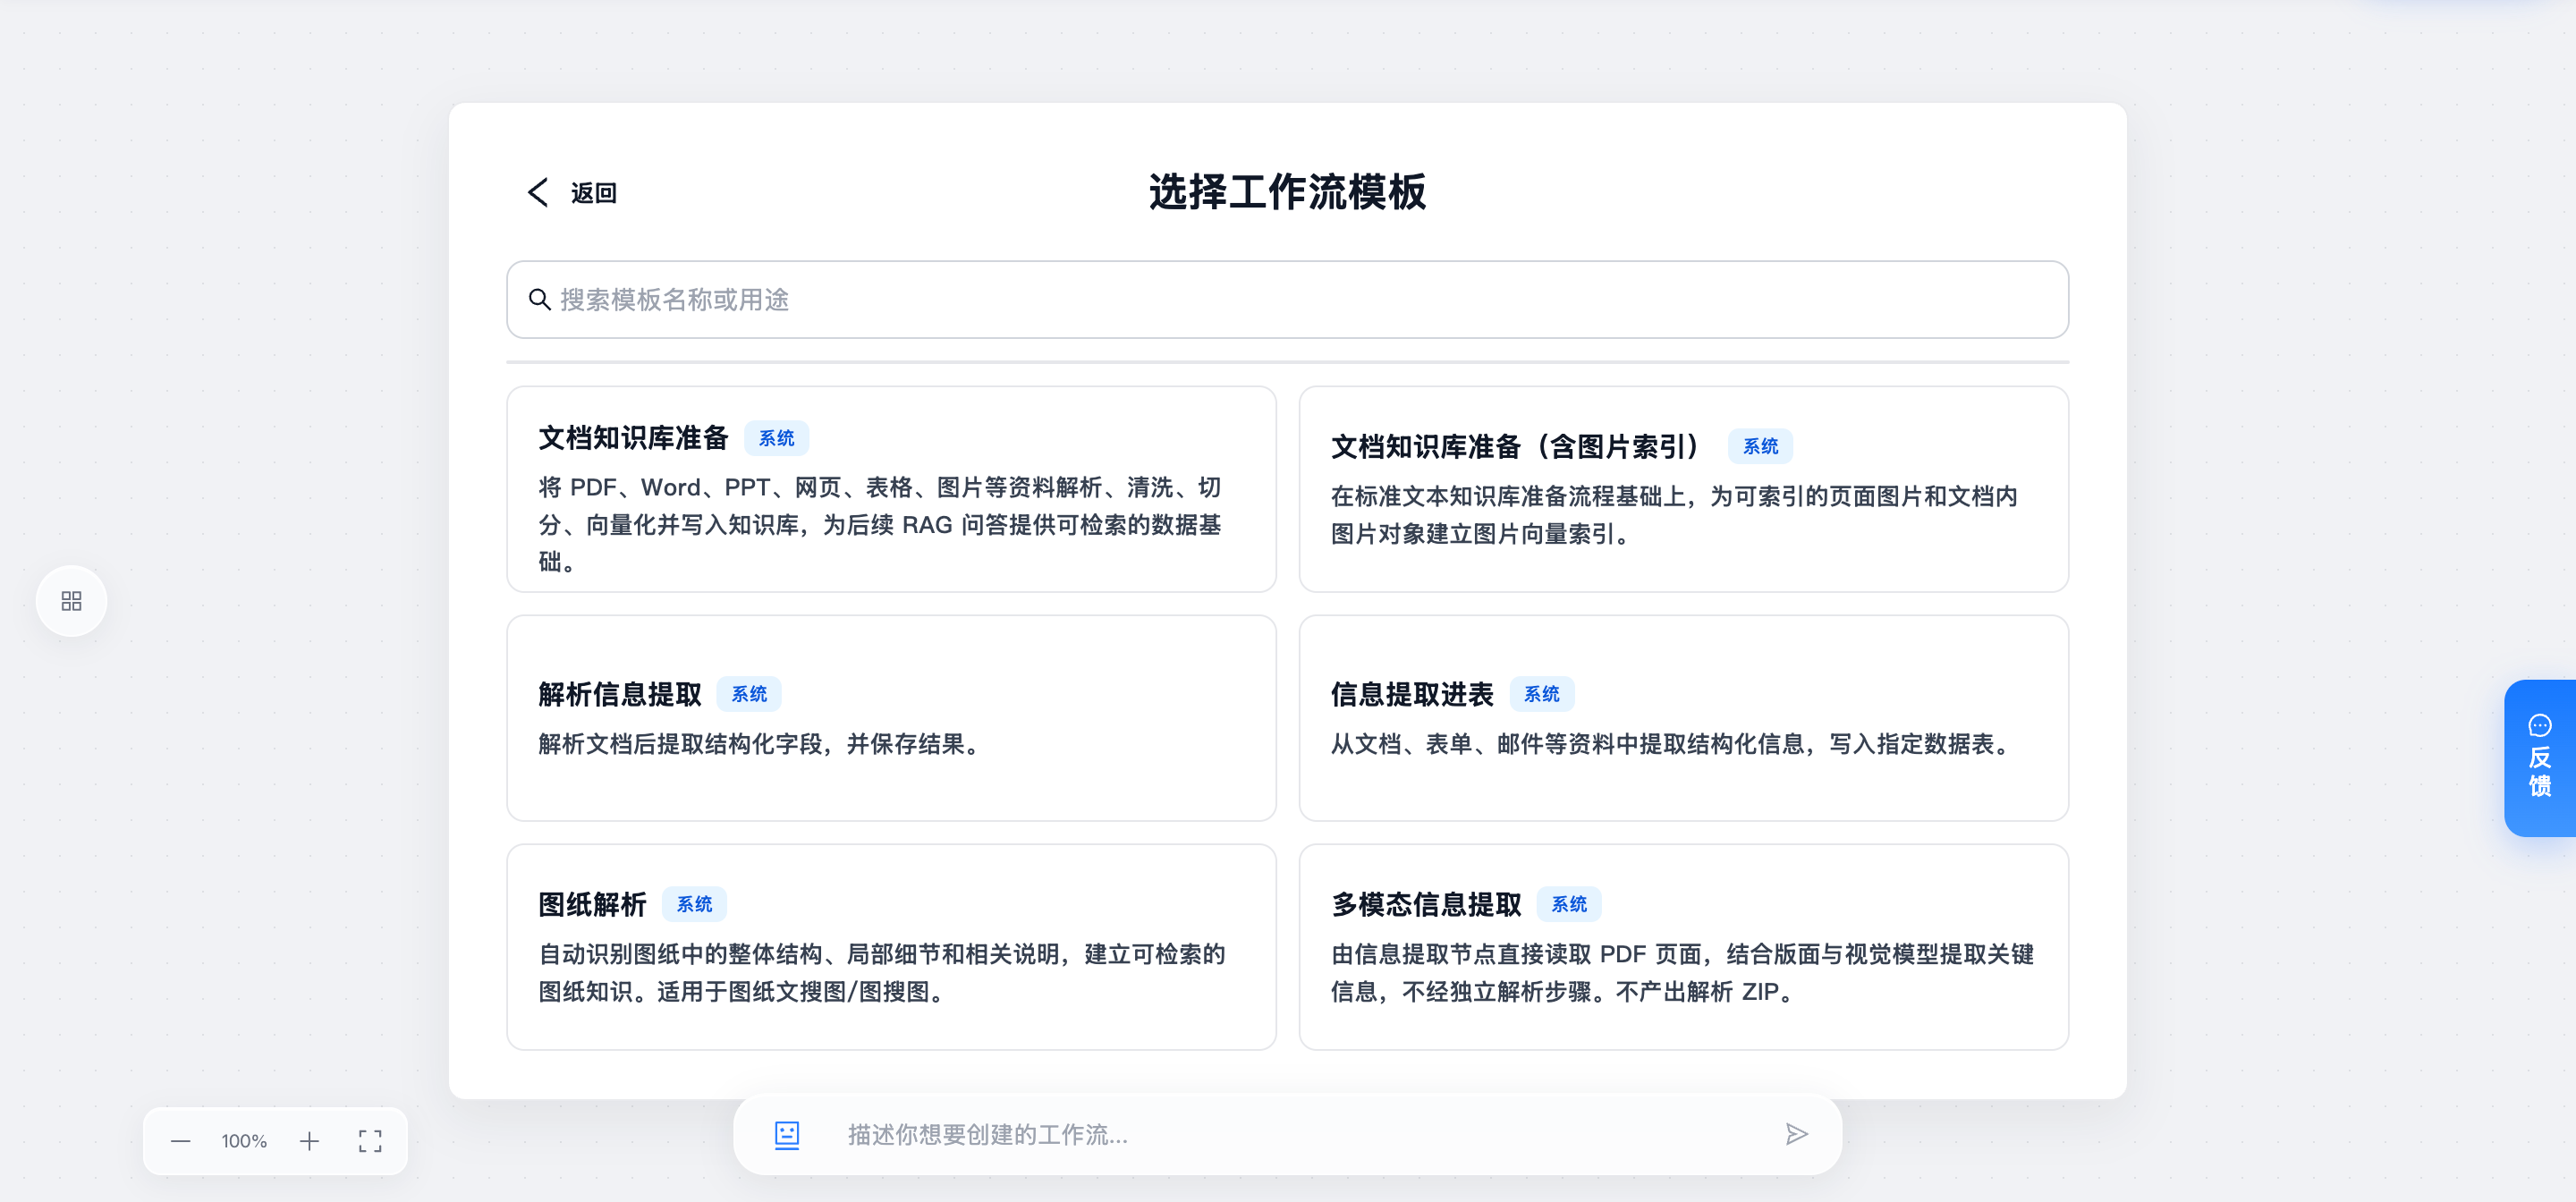
On the workflow creation page, choose the option to start from a template.
Search by name or purpose, such as knowledge base or information extraction.
Select a template to load its steps onto the canvas.
Review node settings and fill in source and target resources in the run form.
Save the parameters, start a manual run, and inspect node outputs and saved results.
For your first file-processing run, use a small sample. Memory Governance is session-triggered; see Memory Governance.
Choose by task
Template |
Purpose |
|---|---|
Write document text to a knowledge base |
|
Build both text and image indexes |
|
Parse documents and save extracted fields |
|
Extract fields into a table |
|
Parse drawings and build text and image indexes |
|
Extract fields directly from PDF pages |
|
Generate training or evaluation samples from rules |
|
Transcribe audio and build a knowledge base index |
|
Transcribe video speech and build a knowledge base index |
|
Filter sessions, extract information, and save memories |
Memory Governance requires the corresponding feature to be enabled. Follow its page after the creation entry becomes available.
Choose between similar templates
Task |
Choice and difference |
|---|---|
Retrieve document text |
Document knowledge base preparation builds a text index and saves parsed files |
Retrieve text and images |
The image-index variant adds visual manifests and image vectors with matching model settings |
Analyze drawing regions and parts |
Drawing Parsing analyzes structure before building text and image indexes |
Extract fields to files |
Document extraction parses first; multimodal extraction reads PDF pages directly and saves JSON |
Write fields to a database |
Table extraction adds a writing step and requires compatible columns |
Retrieve spoken content |
Speech and video templates index transcripts; video does not analyze individual frames |
Generate training or evaluation material |
Dataset Generation needs rules and a schema, followed by sample review |
Retain session memories |
Memory Governance uses synchronized sessions, filtering, extraction, deduplication, and writing |
Check resources before starting
File templates need sources and an output location. Knowledge base templates also need matching indexes and embedding models; table templates need a database and compatible fields. Follow the selected template’s preparation steps and start with a small sample.
Extraction templates combine inputs by default. Do not assume every file produces one row. When changing modes, also check downstream saving bindings. Each template page explains data flow, defaults, and result checks.